This year, the working group will meet at ADT 2026 in Paris , France on Nov. 16-18, 2026. Abstracts are expected by May 18 and full papers by May 25.
Back in 2017, researchers from two startup companies called DeepMind and OpenAI applied preference learning to reinforcement learning, thus ensuring that the latter is guided by a reward function that prefers more human-like behavior. They tested the approach for simulated robotics and Atari gameplay. In both cases, preference data were acquired by showing a small number of video clips about alternative action sequences to human users who ranked these clips according to their preferences.
Whereas this looked like a quite exotic and innocent research project, it should make history. In 2020, researchers at OpenAI applied the same idea to produce human-preferred summaries of texts. Instead of video clips, preference data were acquired by showing alternative text summaries to human users. This work found quite some attention outside its field, but the real seismic moment came in 2022 with the publication of Training language models to follow instructions with human feedback and the subsequent release of a system called ChatGPT. Figure 1 of this paper shows an impressive jump in user acceptance obtained by adding reinforcement learning from human feedback (RLHF) to generative pre-trained transformers.
The unexpected success of ChatGPT then confirmed this jump in user acceptance on a worldwide scale. A technique introduced for making Atari gameplay more human-like thus turned an experimental chatbot into an omnipresent tool. Whereas users needed to be convinced to use such a tool before this shift, they now need to be convinced that those tools should only be used with prudence, if at all.
There is a tendency in machine learning to eliminate intermediate concepts and to prefer end-to-end learning systems that directly map inputs to outputs. For example, face recognition systems directly recognize faces in an image without first recognizing eyes, nose, and mouth. As such, it is no surprise that the multitude of learning systems used in systems like ChatGPT does not please the purists among machine learning researchers. In 2023, researchers from Stanford University proposed a new technique called direct preference optimization (DPO) that shortcuts the whole process and eliminates the learning of a reward model and the usage of reinforcement learning. Their trick consists in transforming a loss function over reward functions into a loss function over policies. In both cases, the loss function is based on preference data. The transformation is possible if preference data are consistent with particular preference models, namely the Bradley-Terry model and the Plackett-Luce model. Whereas the original loss function is used for learning a reward function, the new loss function is directly used for training a policy for next-token prediction that improves an existing language model.
Whereas this elimination of a reward function simplifies the whole learning process, it also makes this process less interpretable since it no longer has an explicit representation of a preference model. There may be many reward functions that are consistent with preference data. RLHF chooses a single reward function, and it is important to understand this choice as it may discard preferred choices of human users.
As direct preference optimization lacks an explicit reward function, it is not completely clear whether the learned policy consistently uses the same implicit reward function when computing a response to a prompt or whether it may use different reward functions for different prompts. The article Direct Preference Optimization: Your Language Model is Secretly a Reward Model includes a discussion of this topic and a characterization of reward functions that are selected by DPO, but the topic may deserve a deeper investigation. It is not fully clear when which choice is made and whether preferred choices of users may be disregarded in unfortunate situations. Questions such as explainability, interpretability, and axiomatic justification of preference models used in large language models may require a deeper theoretical investigation and would be interesting topics for future events on preference handling.
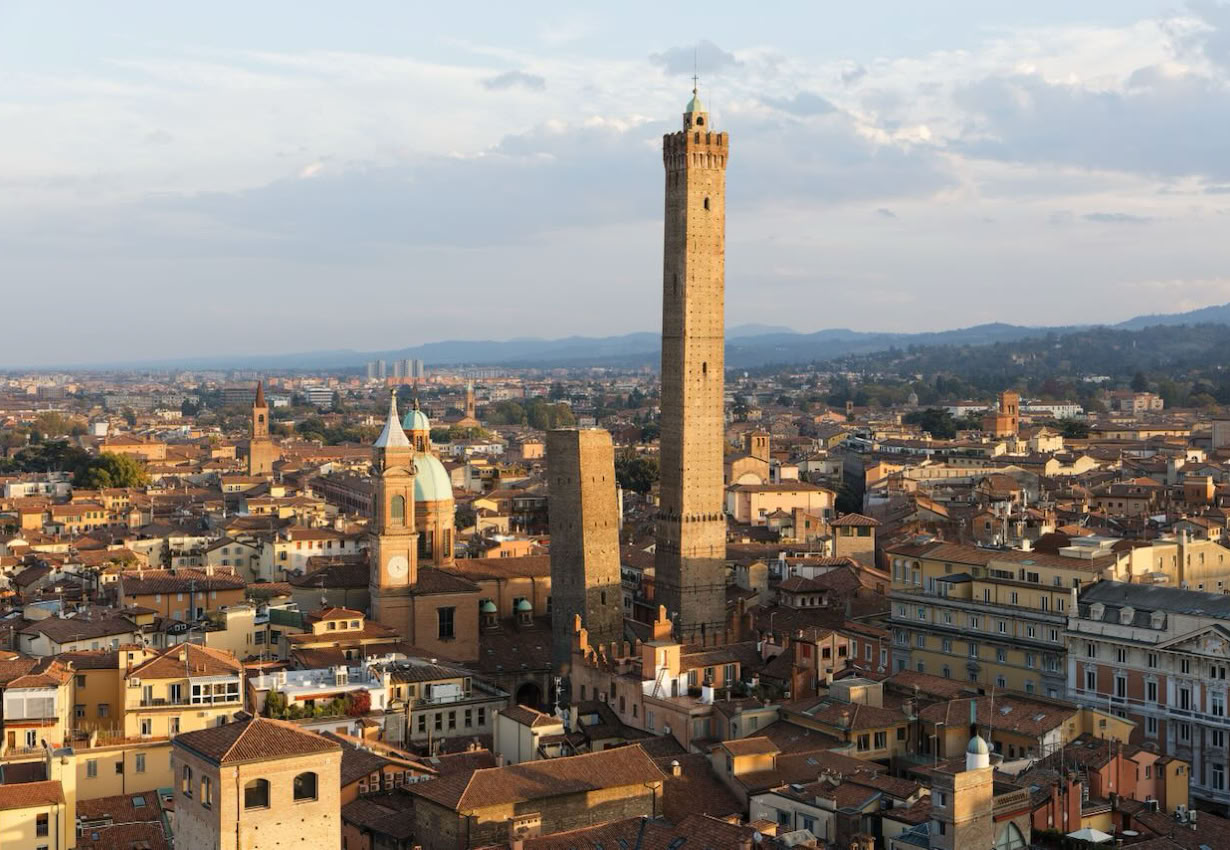
This said, we give a short wrap-up of last year’s workshop on preference handling and an outlook on this year’s events. The 16th Multidisciplinary Workshop on Advances in Preference Handling has been held in Bologna, Italy, on October 25, 2025, in conjunction with ECAI 2025. The workshop has been organized by Khaled Belahcène, Ulrich Junker, and Nimrod Talmon. It featured excellent invited talks by Edith Elkind and by Ulle Endriss and eleven technical presentations. A short report about the workshop has just appeared in the March 2026 issue of the IFORS newsletter.
In 2026, the working group on preference handling is supporting two events. The first event is DA2PL 2026 (From Multiple Criteria Decision Aid to Preference Learning), which will be held at the Université libre de Bruxelles, Belgium, on April 16-17, 2026. The event is organized by Yves De Smet, Marc Pirlot, Gilles Dejaegere, Vinciane De Wilde, Alexandre Flachs, François Verschuren, and Boris Coquelet, and provides a forum for researchers from decision analysis and machine learning to discuss recent advances in the intersection of both fields and to identify new research challenges.
The second event is the 9th International Conference on Algorithmic Decision Theory ADT 2026, which will be held in Paris on November 16-18, 2026. The general chairs are Brice Mayag and Paolo Viappiani, and the program chairs are Lirong Xia and Vincent Mousseau. ADT seeks to bring together researchers and practitioners coming from diverse areas of Computer Science, Economics, and Operations Research in order to improve the theory and practice of modern decision support. Abstracts are expected by May 18, 2026, and full papers by May 25, 2026. Please check the call for papers for details.
Other events of interest for preference handling include the 25th International Conference on Autonomous Agents and Multiagent Systems AAMAS 2026 in Paphos, Cyprus, on May 25-29, 2026; the 28th International Conference on Multiple Criteria Decision Making MCDM 2026 in Wuppertal, Germany, on the same time; the 24th Conference of the International Federation of Operational Research Societies IFORS 2026 in Vienna, Austria, on July 12-17, 2026; and the 35th International Joint Conference on Artificial Intelligence IJCAI-ECAI 2026 in Bremen, Germany, on August 15-21, 2026.